看影片(在新分頁開啟原站)連到 Bilibili・小工蚁创始人
摘要
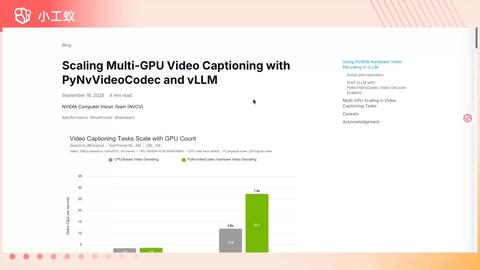
介紹如何提升 vllm 多模態模型在影片推理時的吞吐量。
How to improve the throughput of multimodal model inference for videos using vllm.
這筆內容還沒有取得字幕或內文,這段摘要只根據標題與說明欄產生,可能不夠準確;實際內容請以原站為準。
適合誰看
正在最佳化多模態模型推理效能的開發者。
摘要依據
- 講者
- 張文斌
- 依據
- 標題與說明欄(還沒有取得字幕或內文)
為什麼排在這裡
- 人氣
- 0.12
- 新鮮
- 0.94
在主題頁與搜尋結果裡,名次由相關、人氣、新鮮三個分數決定;這一頁沒有搜尋的關鍵字,所以沒有相關分數。排序怎麼算
相關內容
- Token-Efficient Long Video Understanding for Multimodal LLMs | Paper explained影片 ・ AI Coffee Break with Letitia ・ 9 分鐘
- Scaling Multi-GPU Video Captioning with PyNvVideoCodec and vLLM文章 ・ vLLM Blog
- DeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0文章 ・ vLLM Blog
- How AI Models Scale Beyond a Single GPU Across LLM Workloads影片 ・ IBM Technology ・ 9 分鐘
- Serve Your Own LLM: vLLM & SGLang, End-to-End影片 ・ Vizuara ・ 6 分鐘
- Is Speculative Decoding Worth It? Profiling vLLM on NVIDIA Blackwell — Akamai影片 ・ AI Engineer
摘要由 AI 根據標題與說明欄產生(還沒有取得原文),可能有誤;完整內容請看原站。看影片(在新分頁開啟原站)