文章入門EN
GLM-5.3: How Chinese labs keep stride with the frontier
讀原文(在新分頁開啟原站)連到 Nathan Lambert(部落格)
摘要
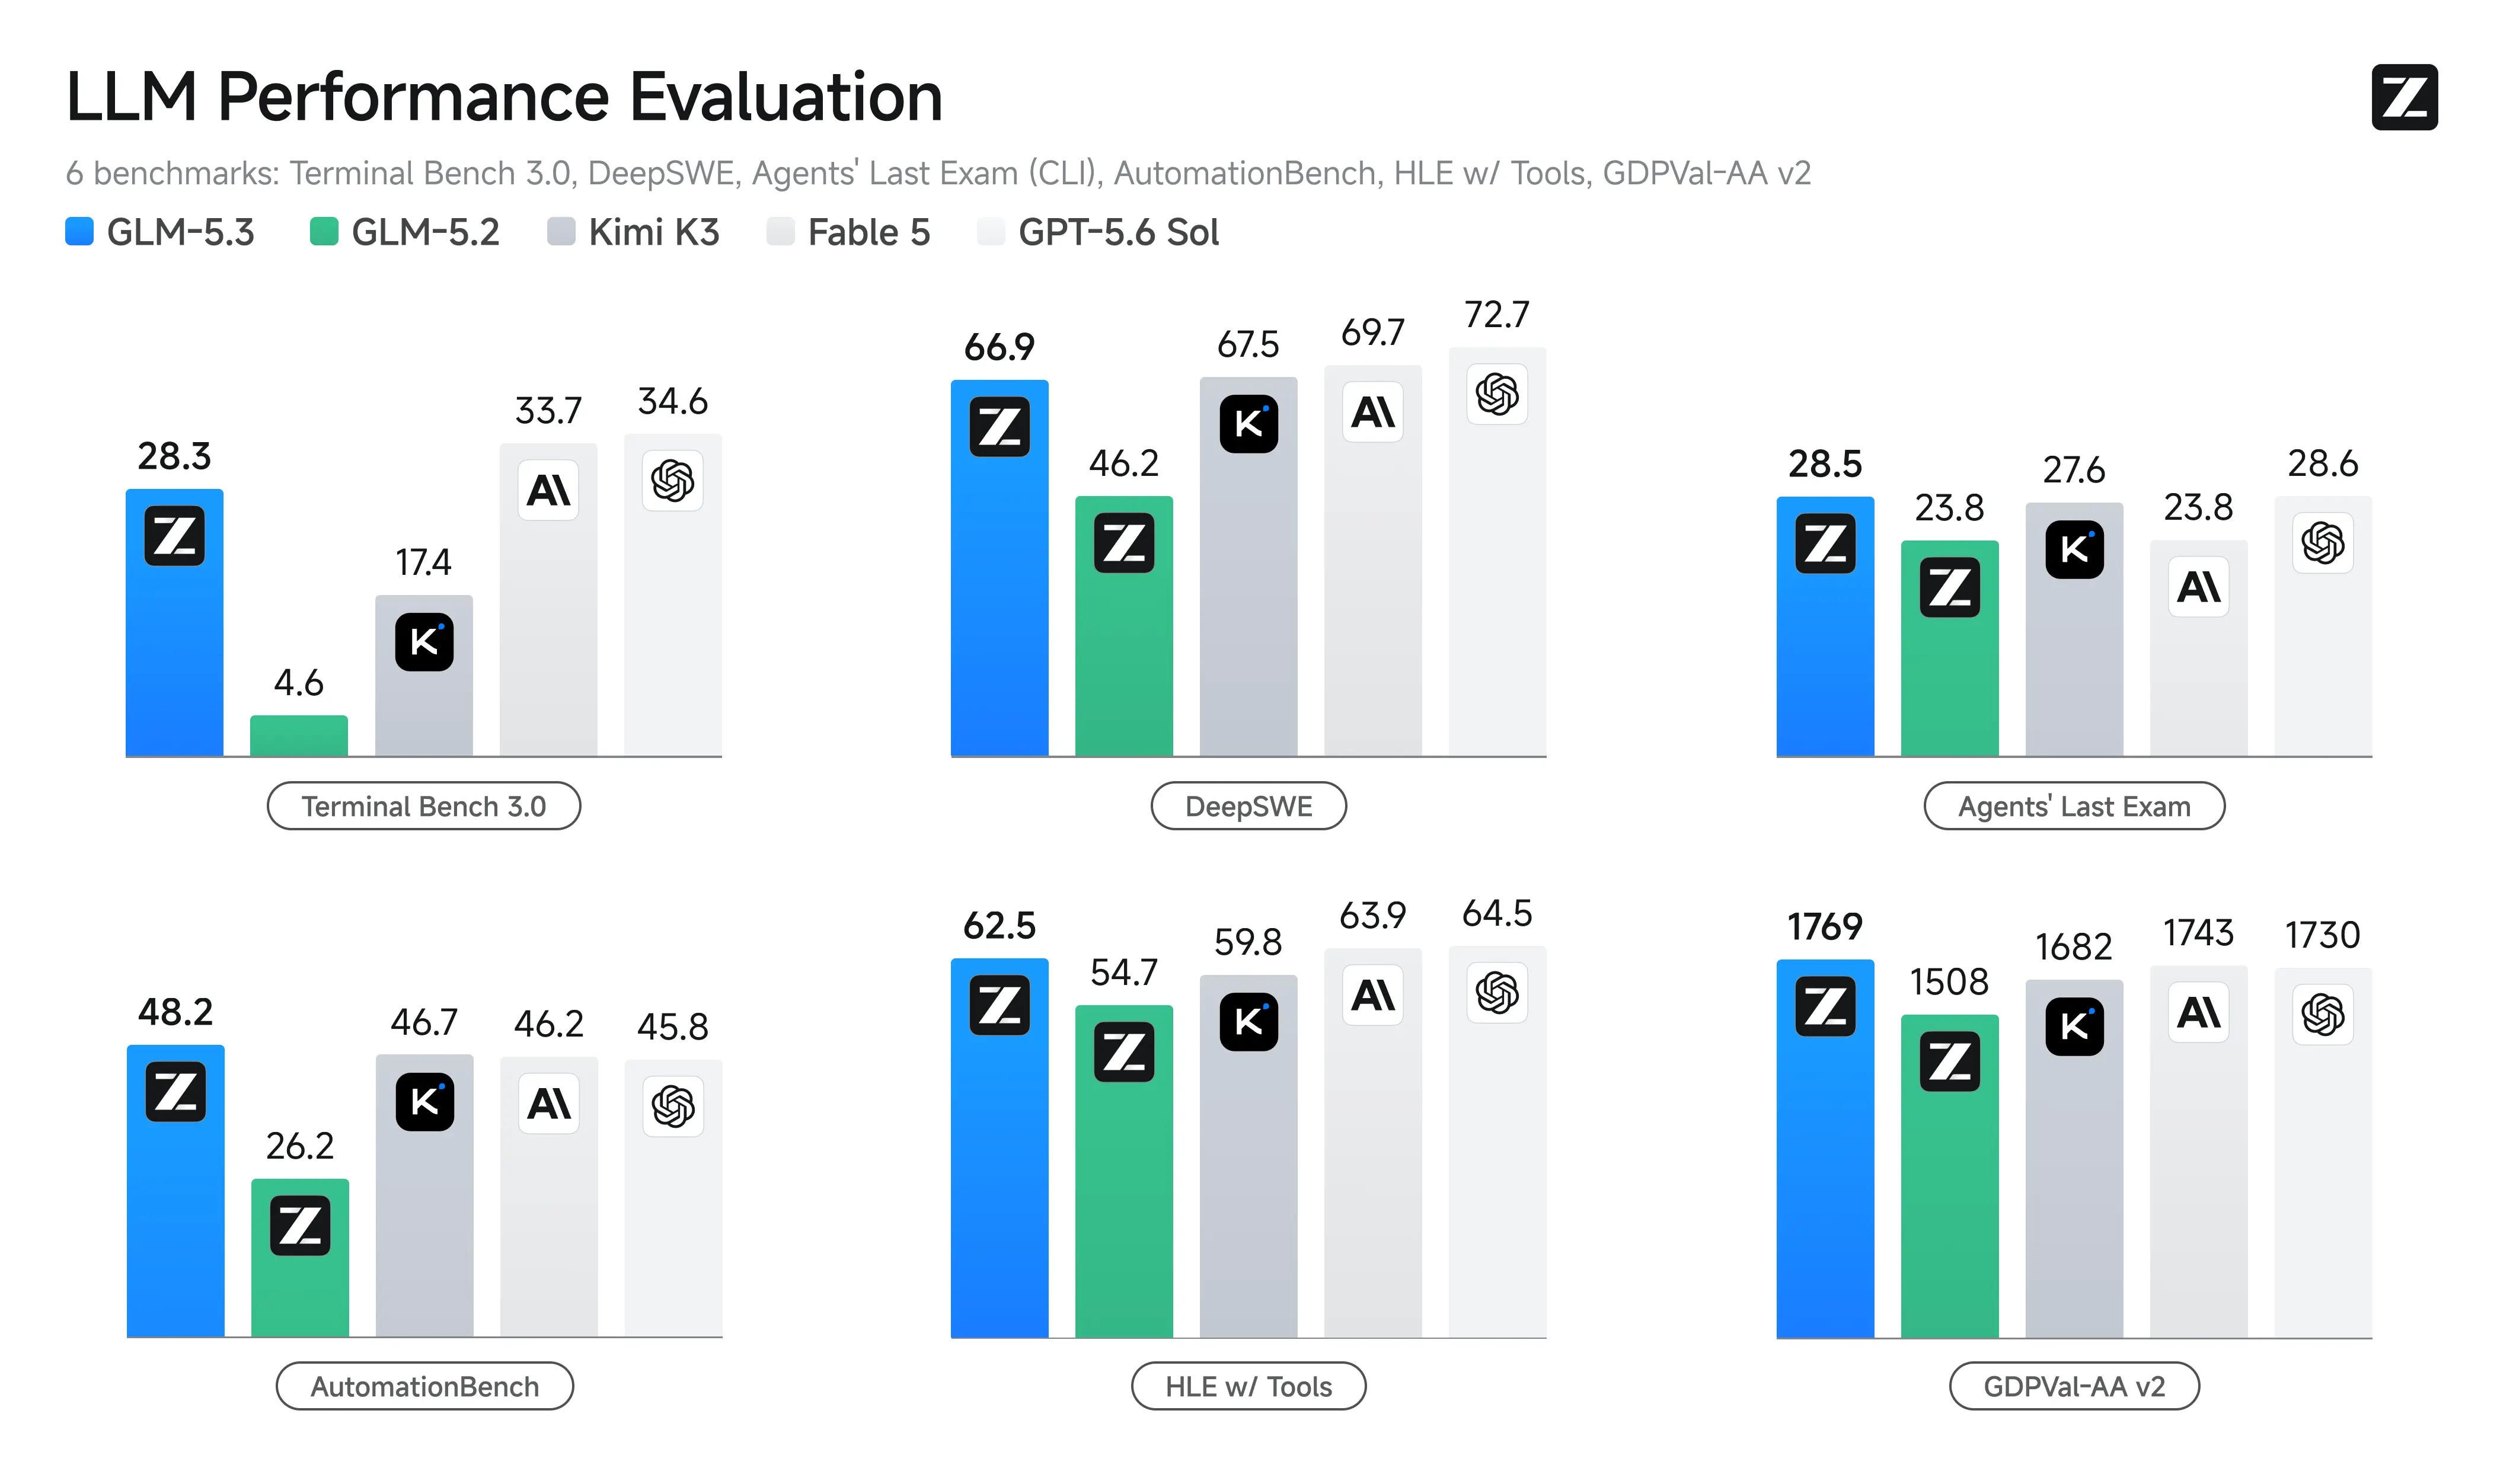
探討中國實驗室如何透過長期訓練與 RL 環境堆疊,在 GLM-5.3 模型上取得領先成績。作者指出,與美國公司相比,中國實驗室更重視在公開測試集上的「benchmaxxing」,並利用快速迭代來維持領先地位。
This article explores how Chinese labs achieved leadership on the GLM-5.3 model through long-term training and RL environment stacking. The author notes that compared to American companies, Chinese labs prioritize 'benchmaxxing' on public test sets and rapid iteration to maintain a leading position.
重點
- Z.ai 透過大量 RL 環境與計算資源,在 GLM-5.3 上取得卓越表現。
- 中國實驗室利用快速預發測試與持續最佳化,維持在前沿技術的領先地位。
- GLM-5.3 在程式碼任務上超越部分美國模型,但視角較窄且未支援視覺能力。
提到的工具與公司
- GLM-5.3
- Z.ai
- OpenAI
- Anthropic
- RL
適合誰看
程式開發者、AI 研究人員、科技業人士。
摘要依據
- 依據
- 文章全文
為什麼排在這裡
- 人氣
- 0.75
- 新鮮
- 0.83
在主題頁與搜尋結果裡,名次由相關、人氣、新鮮三個分數決定;這一頁沒有搜尋的關鍵字,所以沒有相關分數。排序怎麼算
相關內容
- GLM-5.2 is the step change for open agentsPodcast ・ Interconnects ・ 9 分鐘
- GLM-5.2: Open Weights, Near-Frontier Intelligence — Zixuan Li, Z.ai影片 ・ AI Engineer ・ 14 分鐘(在新分頁開啟原站)
- Notes from inside China's AI labsPodcast ・ Interconnects ・ 17 分鐘(在新分頁開啟原站)
- Ep 80: CEO of Surge AI Edwin Chen on Why Frontier Labs Are Diverging, RL Environments & Developing Model TastePodcast ・ Unsupervised Learning ・ 48 分鐘(在新分頁開啟原站)
- Chill week with Qwen 27B and GLM 5.3 beating GPTs, OpenAI announces pausing RL to focus on security and a cancer vaccine being producedPodcast ・ ThursdAI ・ 1 小時 51 分(在新分頁開啟原站)
- GLM-5.2: DeepSeek Was Wrong About RL?影片 ・ bycloud ・ 16 分鐘(在新分頁開啟原站)
摘要由 AI 根據原文產生,可能有誤;完整內容請看原站。讀原文(在新分頁開啟原站)