文章高階EN
Open-world evaluations for measuring frontier AI capabilities
讀原文(在新分頁開啟原站)連到 AI as Normal Technology(Arvind Narayanan、Sayash Kapoor)
摘要
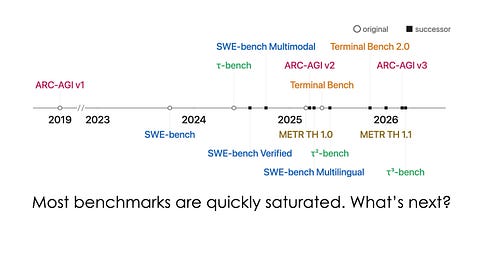
介紹「開放世界評估」,一種超越傳統標榜的 AI 能力測試方法,透過讓 AI 在真實複雜環境中執行任務(如自動開發並上架 iOS 應用程式)來揭露其真實潛力與盲點。文章定義了該評估類別、總結了最佳實踐,並介紹了 CRUX 專案,旨在系統性地追蹤前沿 AI 能力並提供早期警訊。
This paper introduces open-world evaluations, a method for testing AI capabilities in real-world messy tasks like building and publishing an iOS app, and launches the CRUX project to systematically track frontier AI progress.
摘要、重點與章節標題由語言模型整理,細節(誰說的、數字、先後)可能有誤;要引用請以原始內容為準。
重點
- 開放世界評估讓 AI 在真實環境中執行任務,比傳統標榜更能反映真實能力。
- AI 已成功自動完成開發並上架 iOS 應用程式,但過程中仍出現錯誤與需要人工介入。
- 建議評估者公開日誌並明確規範人工介入程度,以改善評估的可重複性與透明度。
提到的工具與公司
- CRUX
- OpenClaw
- iOS App Store
- Apple Developer Account
- Claude Code
- SWE-Bench
- METR
適合誰看
AI 研究者、政策制定者、企業戰略規劃者及關注 AI 風險與治理的專業人士。
摘要依據
- 依據
- 文章全文
為什麼排在這裡
- 人氣
- 0.50
- 新鮮
- 0.51
在主題頁與搜尋結果裡,名次由相關、人氣、新鮮三個分數決定;這一頁沒有搜尋的關鍵字,所以沒有相關分數。排序怎麼算
相關內容
- AI agents can't yet do open-ended AI research文章 ・ AI as Normal Technology(Arvind Narayanan、Sayash Kapoor)
- AI模型的文化盲區─探討AI測試標準的開源現況觀察與難題影片 ・ COSCUP 開源人年會 ・ 31 分鐘
- ⚡️The End of SWE-Bench Verified — Mia Glaese & Olivia Watkins, OpenAI Frontier Evals & Human DataPodcast ・ Latent Space ・ 26 分鐘
- Building standards for the next phase of AI文章 ・ OpenAI News
- Evaluating Open Models with Artificial Analysis | Nemotron Labs影片 ・ NVIDIA Developer
- Chenguang Wang - From Training to Evaluation: Open Recipes for Building Agentic AI at Scale AI影片 ・ Berkeley RDI ・ 12 分鐘
摘要由 AI 根據原文產生,可能有誤;完整內容請看原站。讀原文(在新分頁開啟原站)