文章高階EN
A Visual Guide to Attention Variants in Modern LLMs
讀原文(在新分頁開啟原站)連到 Sebastian Raschka(部落格)
摘要
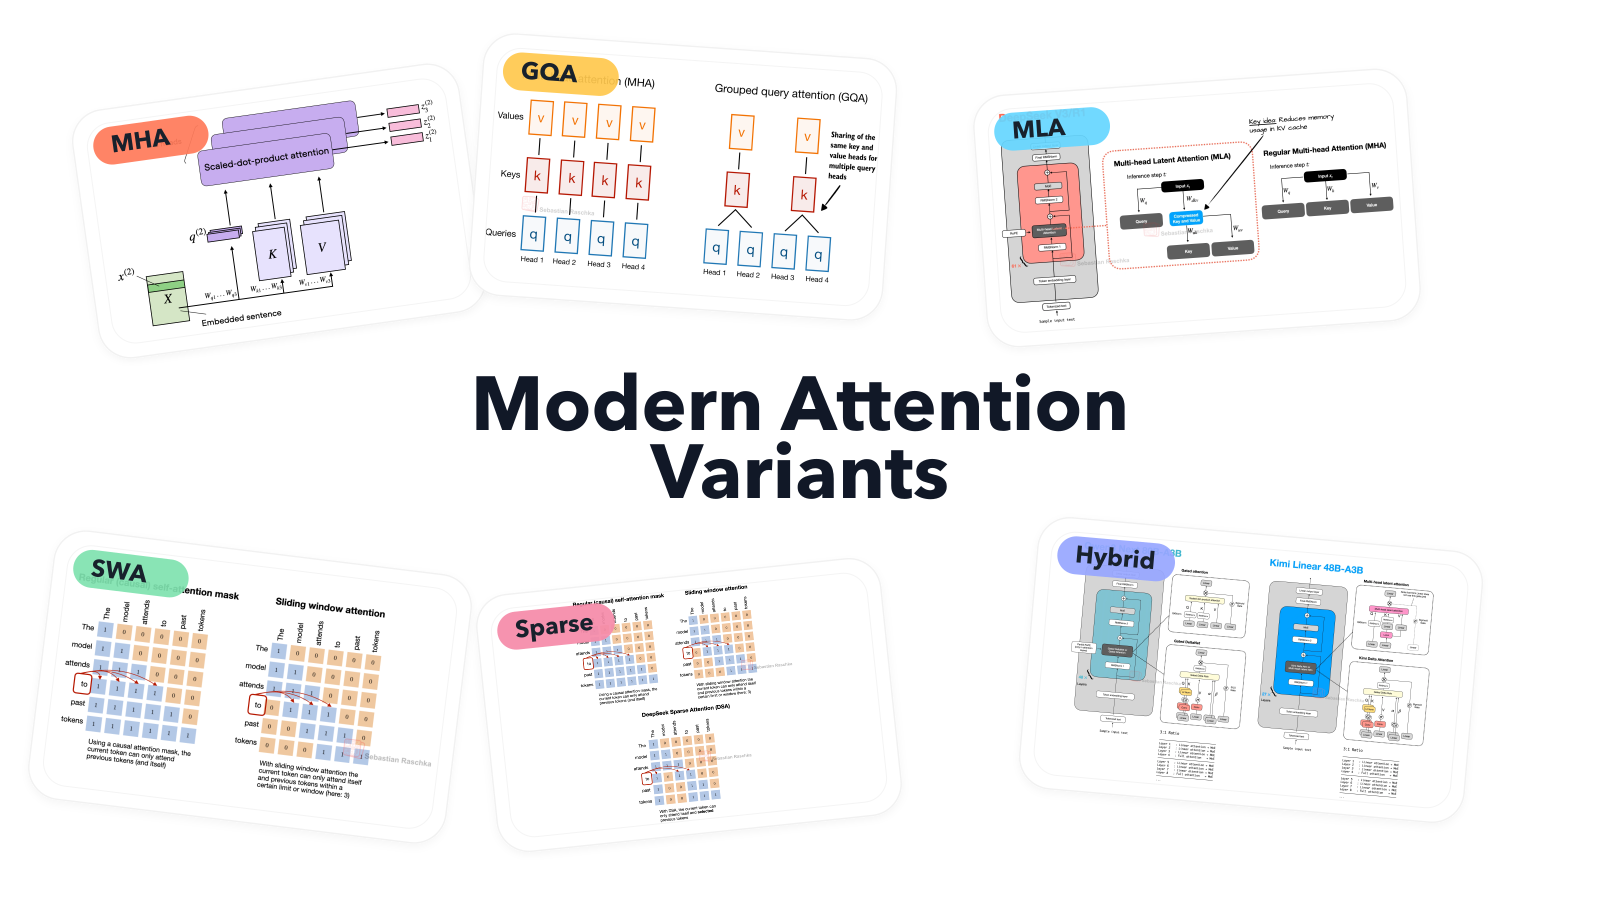
整理了現代大型語言模型中多種注意力變體,包括多頭注意力、GQA、MLA、滑動窗注意力等。透過視覺化模型卡片,讀者可以了解不同架構如何平衡計算效率與模型效能,特別適合想深入理解 LLM 內部機制或選擇合適架構的開發者。
This article reviews various LLM attention variants including Multi-Head Attention, GQA, MLA, and Sliding Window Attention, supported by visual model cards. It explains how these architectures balance computational efficiency with model performance, ideal for developers and researchers interested in…
重點
- 涵蓋多頭注意力、GQA、MLA、滑動窗注意力等主流變體。
- 透過視覺卡片展示各架構的例項與設計邏輯。
- 探討計算效率與模型效能之間的平衡策略。
提到的工具與公司
- GQA
- MLA
- Gated DeltaNet
- Mamba-2
- MoE
- Latent MoE
- MTP
適合誰看
程式開發者、AI 研究人員、模型架構師。
摘要依據
- 依據
- 文章全文
為什麼排在這裡
- 人氣
- 0.75
- 新鮮
- 0.47
在主題頁與搜尋結果裡,名次由相關、人氣、新鮮三個分數決定;這一頁沒有搜尋的關鍵字,所以沒有相關分數。排序怎麼算
相關內容
- Beyond Standard LLMs文章 ・ Sebastian Raschka(部落格)
- A Visual Guide to Attention Mechanisms in LLMs - Luis Serrano, Data Hack 2025 with @Analytics Vidhya影片 ・ Luis Serrano Academy ・ 52 分鐘(在新分頁開啟原站)
- Recent Developments in LLM Architectures: KV Sharing, mHC, and Compressed Attention文章 ・ Sebastian Raschka(部落格)
- A Visual Tour of Modern LLM Architectures影片 ・ Sebastian Raschka ・ 39 分鐘(在新分頁開啟原站)
- Build an LLM from Scratch 3: Coding attention mechanisms影片 ・ Sebastian Raschka ・ 2 小時 16 分(在新分頁開啟原站)
- Recurrence and Attention for Long-Context Transformers with Jacob Buckman - #750Podcast ・ The TWIML AI Podcast ・ 57 分鐘(在新分頁開啟原站)
摘要由 AI 根據原文產生,可能有誤;完整內容請看原站。讀原文(在新分頁開啟原站)