讀原文(在新分頁開啟原站)連到 Sebastian Raschka(部落格)
摘要
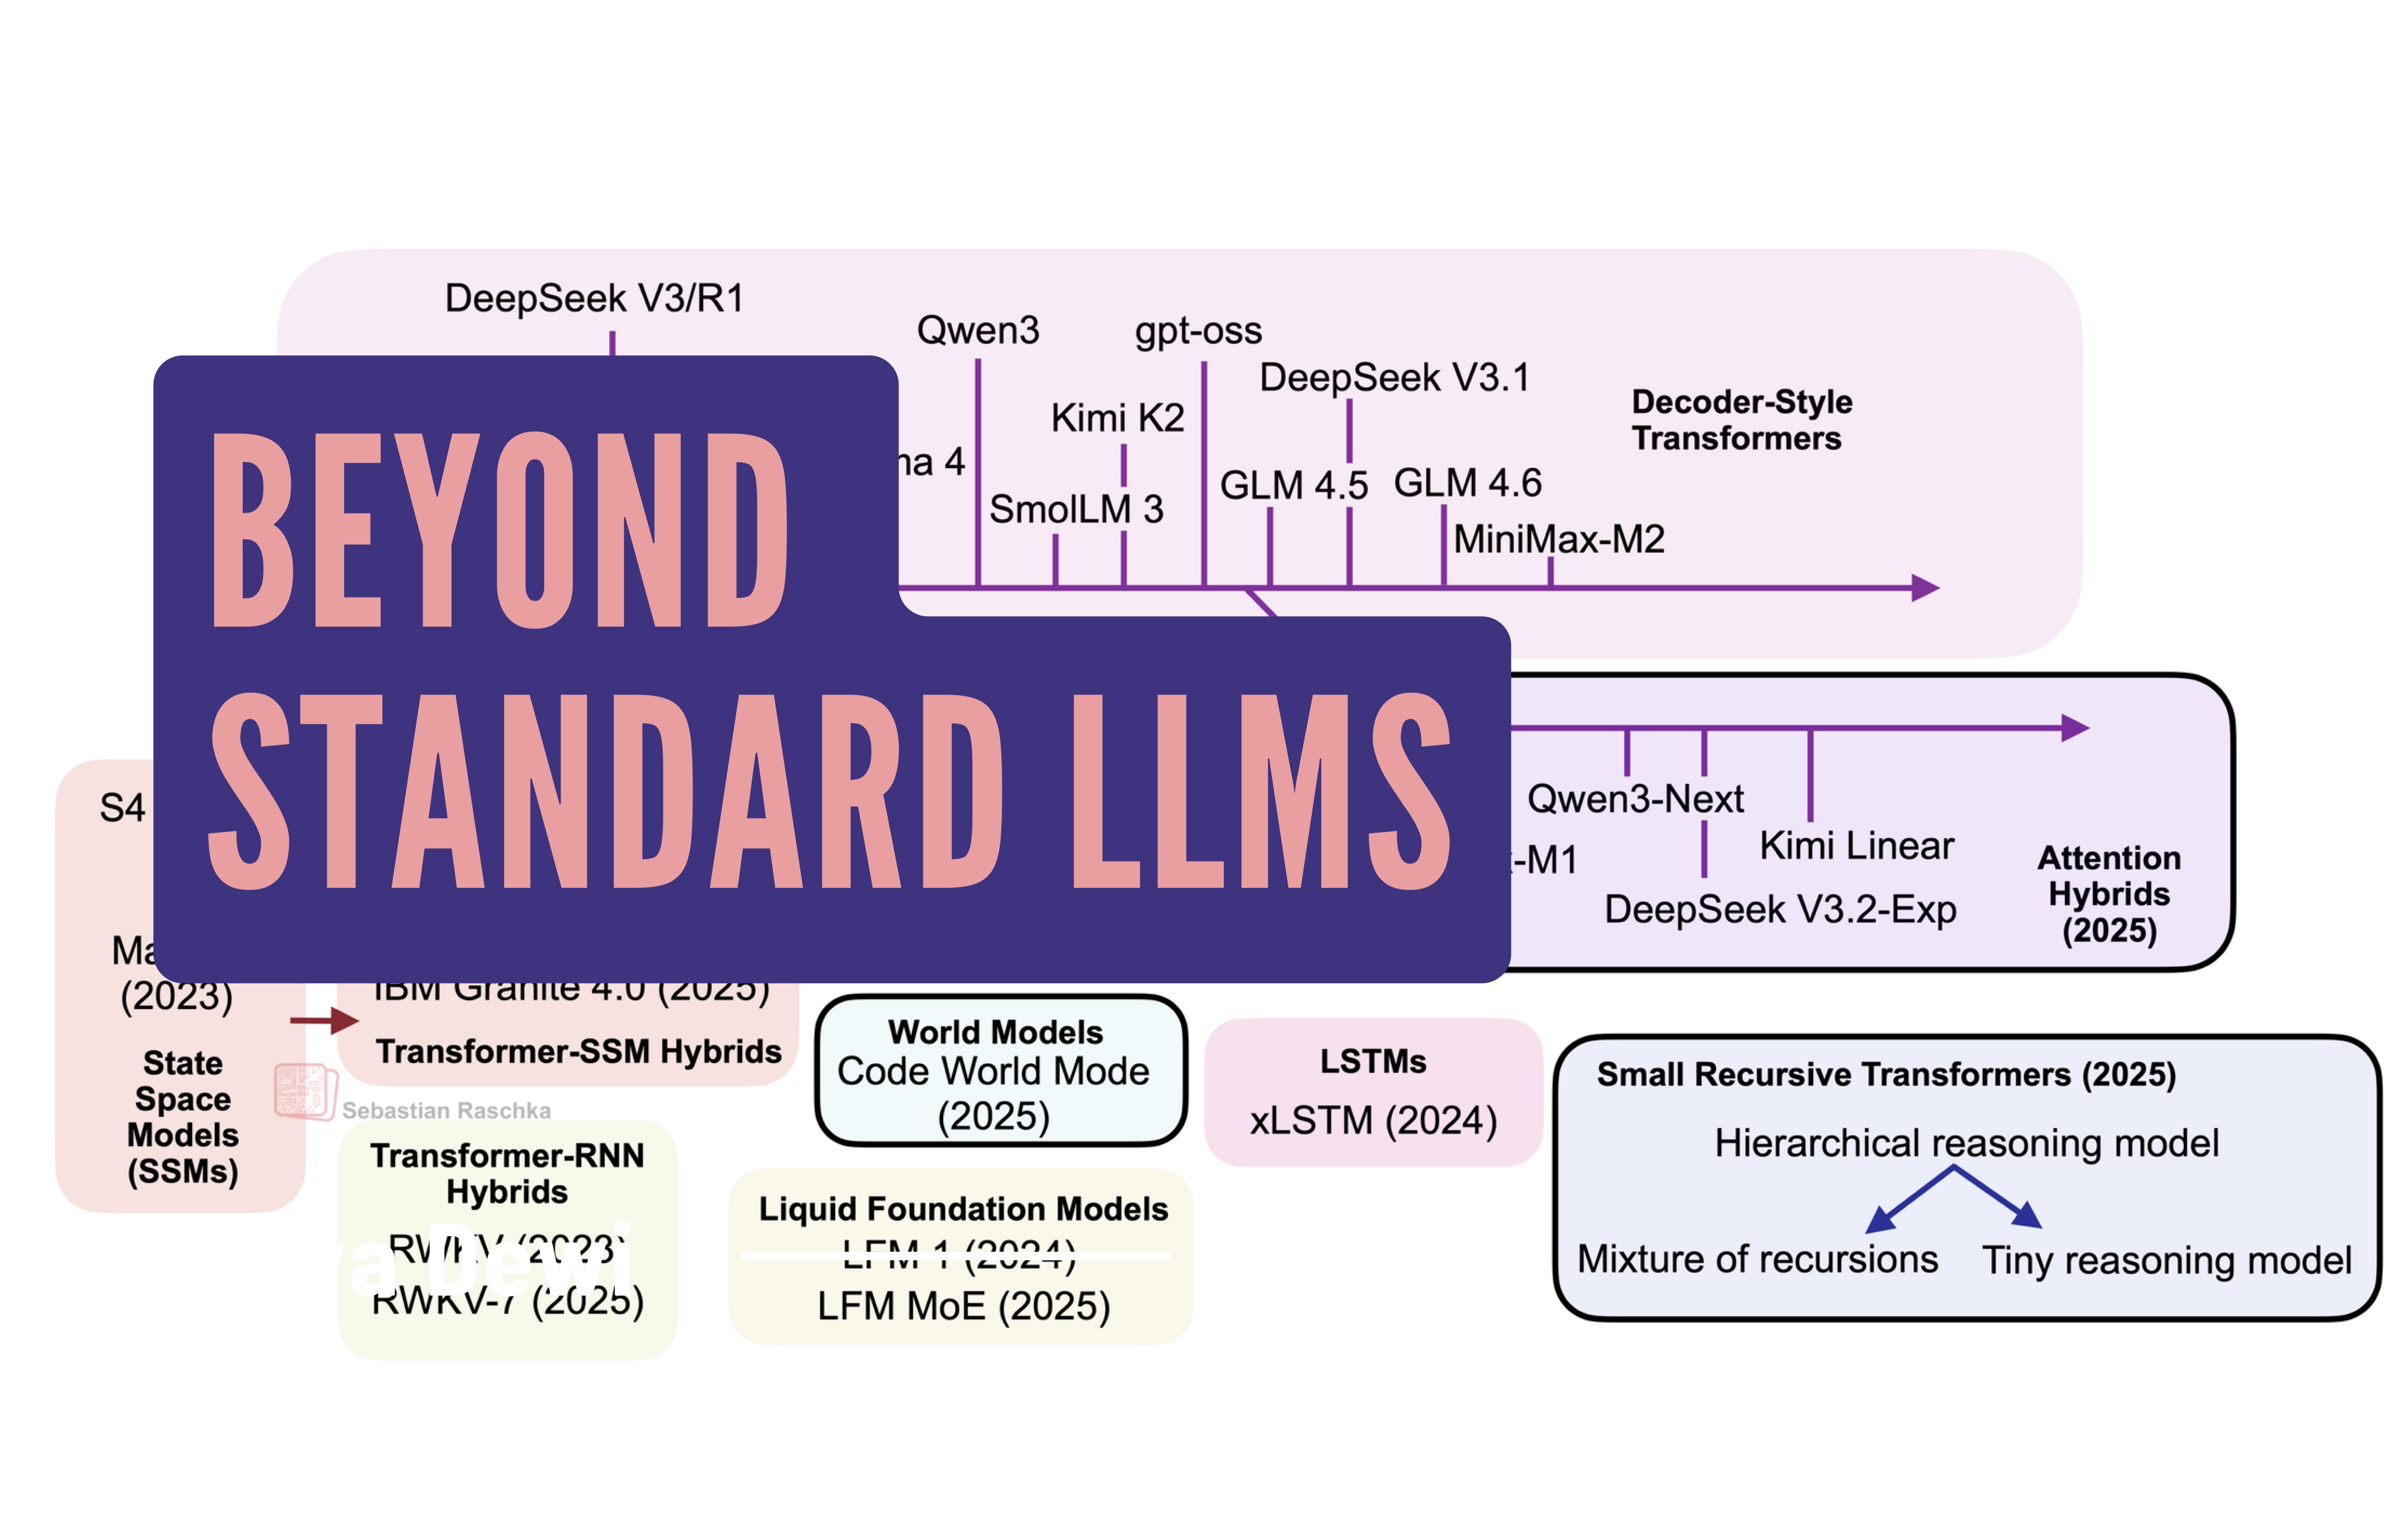
探討了超越傳統自回歸 LLM 的幾種新興架構,包括線性注意力混合模型、文字擴散模型以及小規模迴歸 Transformer。作者指出,雖然自回歸模型目前仍是效能最優且工具鏈成熟的選擇,但線性注意力混合模型在長上下文效率上表現出色,而文字擴散模型則提供了並行生成的潛力。
This article explores emerging architectures beyond traditional autoregressive LLMs, including linear attention hybrids, text diffusion models, and small recursive transformers. While autoregressive models remain the current state-of-the-art, linear attention hybrids offer significant efficiency for…
重點
- 線性注意力混合模型如 Qwen3-Next 和 DeepSeek V3.2,用 Gated DeltaNet 取代傳統注意力,大幅降低長上下文計算成本。
- 文字擴散模型如 LLaDA 允許並行生成多個 token,無需序列依賴,但無法流式輸出。
- 小規模迴歸 Transformer 專為特定推理任務設計,如數學或邏輯謎題,但尚未取代通用大模型。
提到的工具與公司
- Qwen3-Next
- DeepSeek V3.2
- MiniMax-M1
- LLaDA
- Gated DeltaNet
適合誰看
對 AI 架構感興趣、希望了解長上下文處理效率或並行生成技術的開發者與研究者。
摘要依據
- 依據
- 文章全文
為什麼排在這裡
- 人氣
- 0.75
- 新鮮
- 0.28
在主題頁與搜尋結果裡,名次由相關、人氣、新鮮三個分數決定;這一頁沒有搜尋的關鍵字,所以沒有相關分數。排序怎麼算
相關內容
- Recent Developments in LLM Architectures: KV Sharing, mHC, and Compressed Attention文章 ・ Sebastian Raschka(部落格)
- Olmo Hybrid and future LLM architecturesPodcast ・ Interconnects ・ 11 分鐘(在新分頁開啟原站)
- A Visual Guide to Attention Variants in Modern LLMs文章 ・ Sebastian Raschka(部落格)
- 【生成式AI導論 2024】第10講:今日的語言模型是如何做文字接龍的 — 淺談Transformer (已經熟悉 Transformer 的同學可略過本講)影片 ・ Hung-yi Lee ・ 38 分鐘(在新分頁開啟原站)
- Build an LLM from Scratch 3: Coding attention mechanisms影片 ・ Sebastian Raschka ・ 2 小時 16 分(在新分頁開啟原站)
- LLM Building Blocks & Transformer Alternatives影片 ・ Sebastian Raschka ・ 27 分鐘(在新分頁開啟原站)
摘要由 AI 根據原文產生,可能有誤;完整內容請看原站。讀原文(在新分頁開啟原站)