文章高階EN
Recent Developments in LLM Architectures: KV Sharing, mHC, and Compressed Attention
讀原文(在新分頁開啟原站)連到 Sebastian Raschka(部落格)
摘要
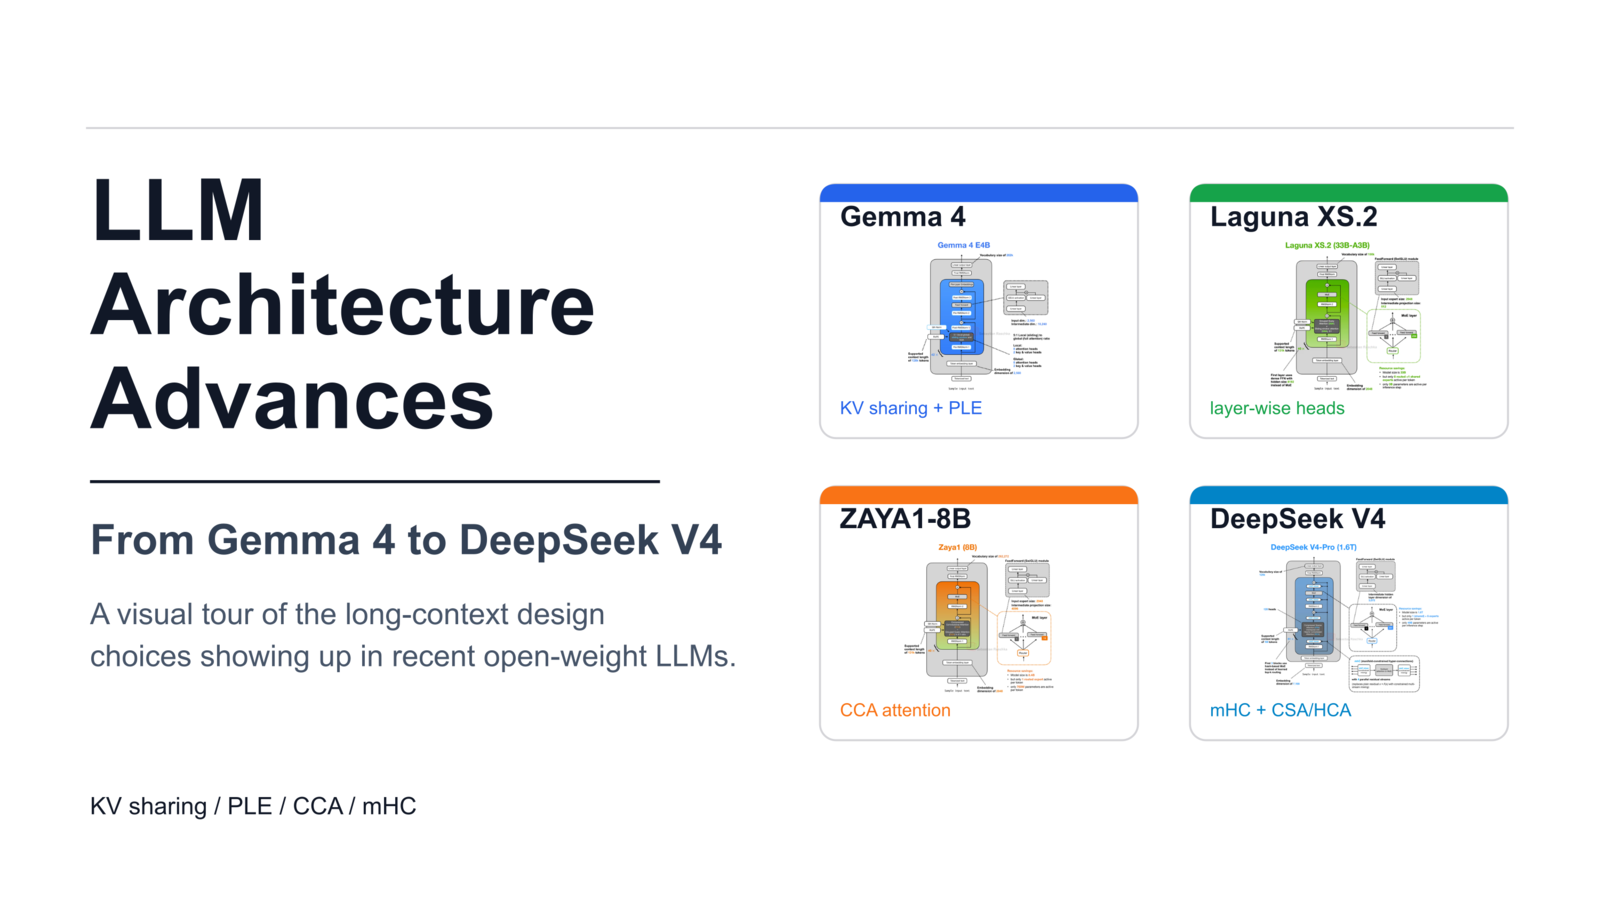
介紹了近期開源大語言模型(LLM)在長文處理效率上的幾項重要架構創新。主要涵蓋了 Gemma 4 的跨層 KV 共享與每層嵌入、Laguna XS.2 的層級注意力預算、ZAYA1-8B 的壓縮凸積注意力,以及 DeepSeek V4 的壓縮長文注意力機制。這些技術旨在減少計算資源與記憶體消耗,特別適合推理模型與 Agent 工作流,讓使用者能處理更長的上下文而不必大幅增加模型引數。
This article reviews recent architectural innovations in open-weight LLMs designed for long-context efficiency. Key topics include Gemma 4's cross-layer KV sharing and per-layer embeddings, Laguna XS.2's layer-wise attention budgeting, ZAYA1-8B's compressed convolutional attention, and DeepSeek V4's…
重點
- Gemma 4 採用跨層 KV 共享與每層嵌入,大幅縮減長文記憶體與計算成本。
- ZAYA1-8B 引入壓縮凸積注意力,在壓縮的潛在空間中執行注意力計算。
- DeepSeek V4 結合壓縮長文注意力與稀疏注意力,在 1M 上下文下顯著降低 FLOPs 與 KV 記憶體。
提到的工具與公司
- Gemma 4
- DeepSeek V4
- Laguna XS.2
- ZAYA1-8B
- GQA
- MLA
- MoE
適合誰看
對 LLM 架構感興趣的程式開發者、AI 研究者或希望最佳化推理效能的開發人員。
摘要依據
- 講者
- Sebastian Raschka
- 依據
- 文章全文
為什麼排在這裡
- 人氣
- 0.75
- 新鮮
- 0.59
在主題頁與搜尋結果裡,名次由相關、人氣、新鮮三個分數決定;這一頁沒有搜尋的關鍵字,所以沒有相關分數。排序怎麼算
相關內容
- Beyond Standard LLMs文章 ・ Sebastian Raschka(部落格)
- Olmo Hybrid and future LLM architecturesPodcast ・ Interconnects ・ 11 分鐘(在新分頁開啟原站)
- A Visual Guide to Attention Variants in Modern LLMs文章 ・ Sebastian Raschka(部落格)
- Open challenges in LLM research文章 ・ Chip Huyen(部落格)
- What I Learned From Implementing LLM Architectures From Scratch (And How to Get Started)影片 ・ Sebastian Raschka ・ 53 分鐘(在新分頁開啟原站)
- LLaMA explained: KV-Cache, Rotary Positional Embedding, RMS Norm, Grouped Query Attention, SwiGLU影片 ・ Umar Jamil ・ 1 小時 11 分(在新分頁開啟原站)
摘要由 AI 根據原文產生,可能有誤;完整內容請看原站。讀原文(在新分頁開啟原站)