讀原文(在新分頁開啟原站)連到 vLLM Blog
摘要
介紹如何使用 Speculators 庫與 Mooncake 傳輸引擎,在 GB300 NVL72 硬體上訓練 Kimi-K3 的 DSpark 推測解碼模型。讀者可學習如何整合開源工具進行大規模模型訓練,並提升推理效能與吞吐量。
This article details training the Kimi-K3 DSpark model using Speculators and Mooncake on GB300 hardware to boost inference speed.
摘要、重點與章節標題由語言模型整理,細節(誰說的、數字、先後)可能有誤;要引用請以原始內容為準。
重點
- 介紹 DSpark 如何結合並行推測與序列校正提升推理速度。
- 說明 Mooncake 如何解決大模型訓練時的視訊記憶體與傳輸限制。
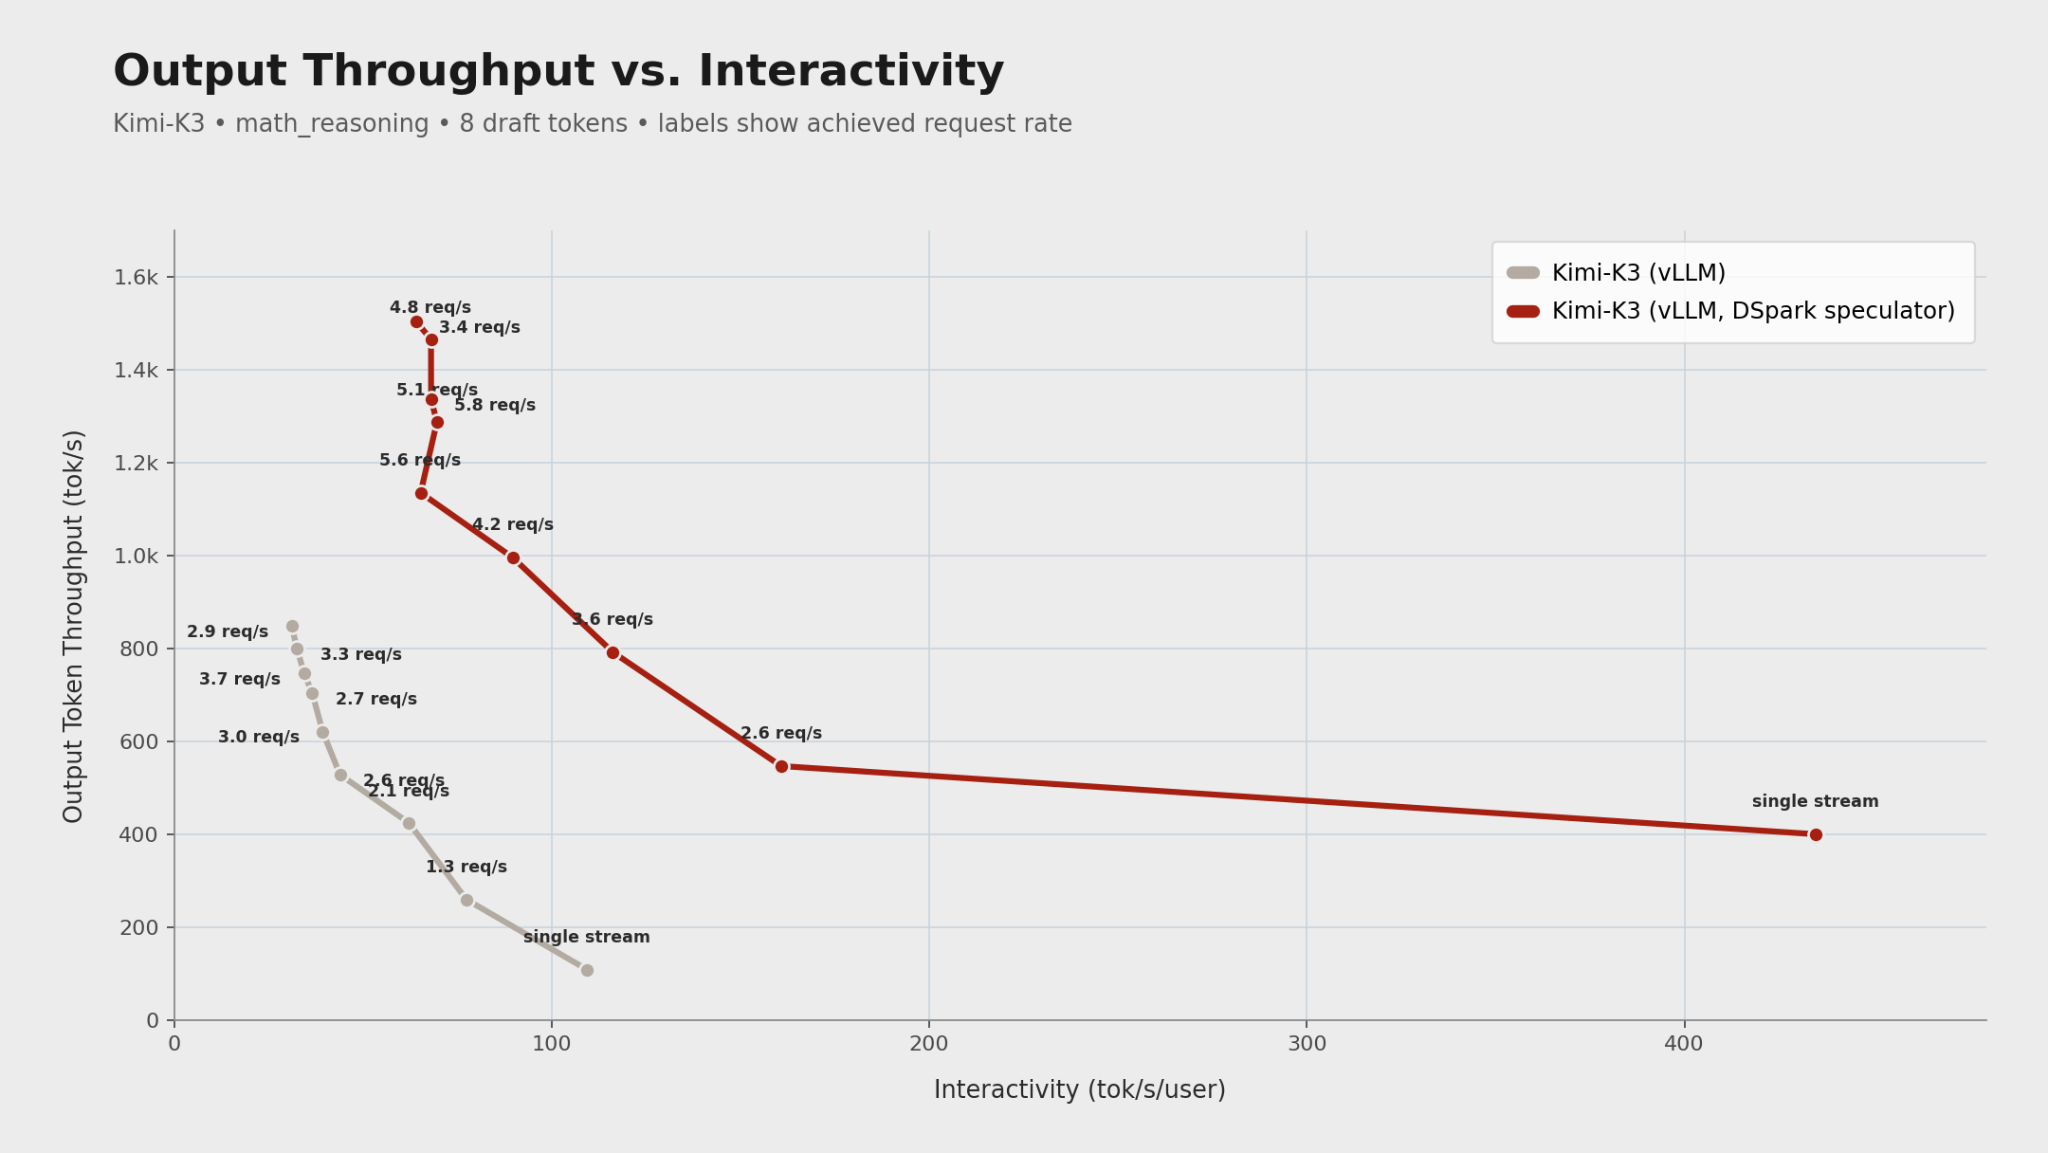
- 展示在 GB300 硬體上訓練 Kimi-K3 的實際效能資料。
提到的工具與公司
適合誰看
具備機器學習或大型語言模型開發經驗的研究人員與工程師。
摘要依據
- 依據
- 文章全文
為什麼排在這裡
- 人氣
- 0.50
- 新鮮
- 0.91
在主題頁與搜尋結果裡,名次由相關、人氣、新鮮三個分數決定;這一頁沒有搜尋的關鍵字,所以沒有相關分數。排序怎麼算
相關內容
- Kimi K3 Is Here: Efficient Day-0 Support on vLLM文章 ・ vLLM Blog
- Kimi K3 by Moonshot now available on Modal文章 ・ Modal Blog
- not much happened today文章 ・ AINews(Latent Space/smol.ai)
- What's New in Inference Engineering — Philip Kiely, Baseten影片 ・ AI Engineer ・ 19 分鐘
- Stanford CS336 Language Modeling from Scratch | Spring 2026 | Guest Lecture: Dan Fu影片 ・ Stanford Online ・ 1 小時 12 分
- Kimi K3 Performance Optimizations in vLLM: The Road to 2.8× Throughput文章 ・ vLLM Blog
摘要由 AI 根據原文產生,可能有誤;完整內容請看原站。讀原文(在新分頁開啟原站)